Hugging Face Daily Papers has listed a preprint titled "ACCRUE: Continual Off-Policy Reinforcement Learning for Robot Foundation Models" (arXiv 2610.18596). The source is an aggregation page for research publications; whether it counts as an official body cannot be confirmed from the available metadata.
What the paper proposes
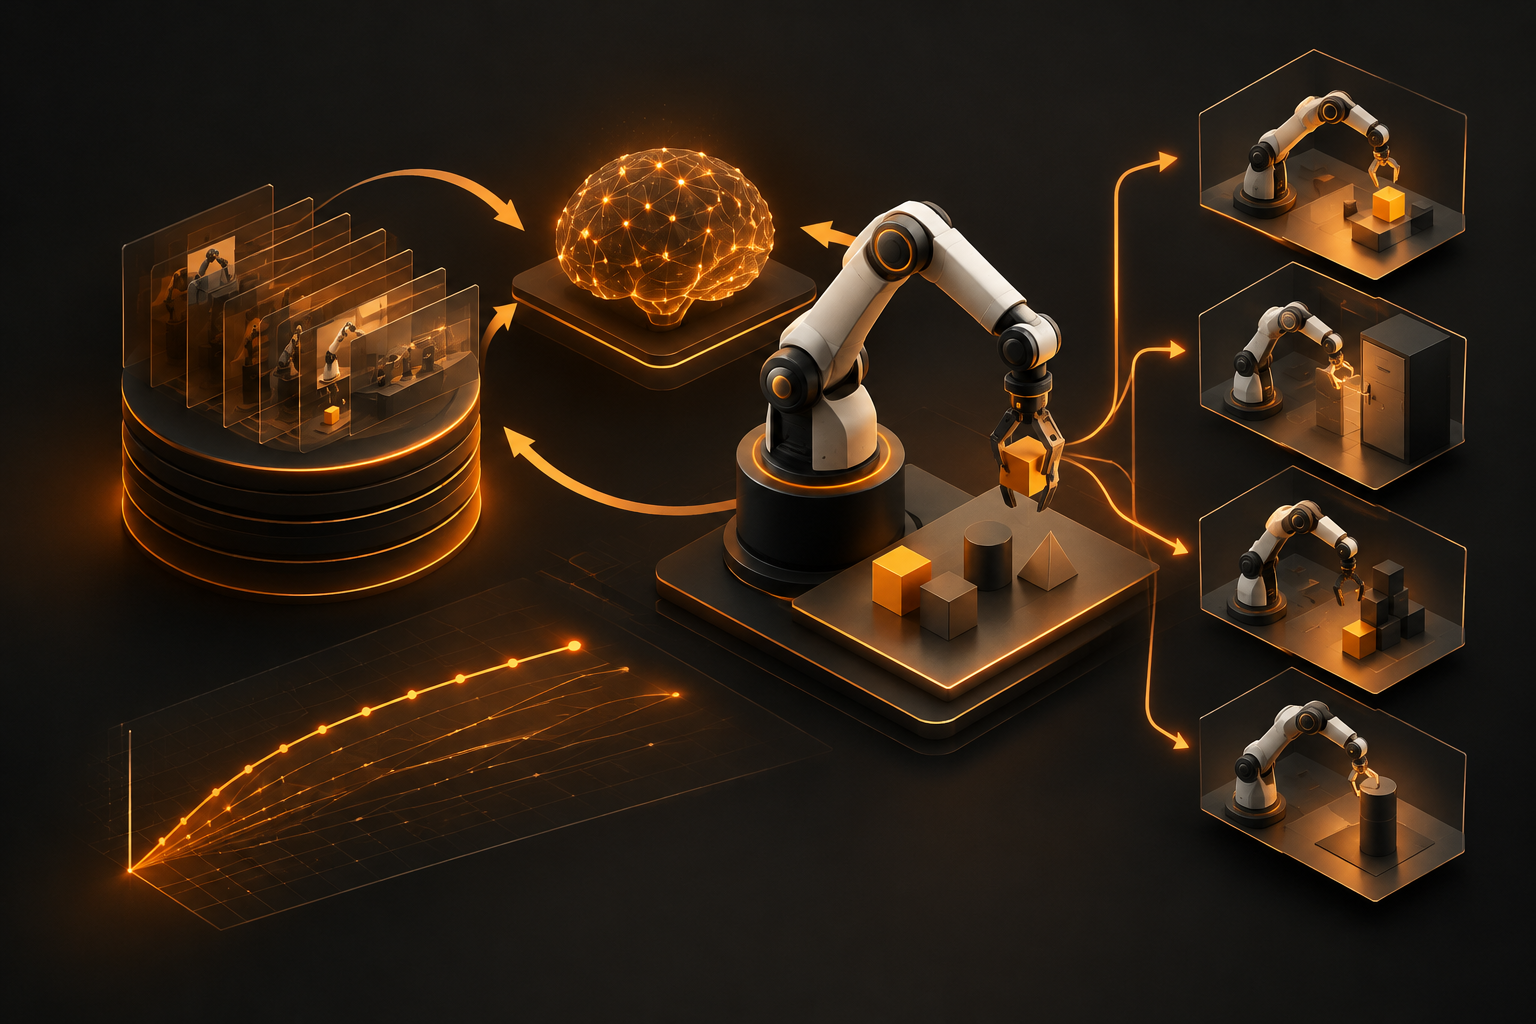
The authors describe a reinforcement learning method for robot foundation models that carries lightweight actor and critic networks from one task to the next. According to the summary, each stage is meant to reuse behavioral and value knowledge from earlier RL. Earlier behaviors are preserved by distilling the actor toward cached targets on a small number of retained episodes.
Reported results
According to the abstract, the method accelerates learning of subsequent tasks with near-zero forgetting, both in simulation and on real robot hardware for contact-rich assembly sequences. Real-robot training time is said to fall by 31.0% to 68.5%.
Context
These figures come from the abstract of a preprint and have not been independently verified. For German companies with robotic assembly, such an approach could become relevant if the results are confirmed beyond the author group. It remains open how stable the methods are across many tasks and hardware types.
Sources
Editorially owned by Ideal Syka. Sources and method: Newsroom & method. Tips and corrections: ai@i6eal.de.